AI Video Generation - General Discussion, Tips, Tricks, Frustrations and Showcases

To me, among the open models, there's just nothing like Minimax H3 (and its variants). Natively, it's not optimized for naughty stuff, but there are ways around that, and some alternative merges that allow for some nice stuff. Granted, I don't toy too much with realistic imagery, though it can be competent for that too. If you have lots of VRAM, it can generate some stunning videos in HD, 2K and above.
 
  • Like
Reactions: Casshern2
I only have a 12GB 3060 so I'd have to use H3 with certain versions and optimizations to even give that ago. I do plan to look into it. If you've been playing around with it, anything you'd be willing to share?
 
I found a 1 year old YouTube video of a workflow with a custom node pack the guy created to help build longer videos. I tried it, after working out how to install the node pack, and it basically works, but it takes the last frame of a generated video and uses it as the first frame of the next. You know the drill. That comes with the same old obvious pitfall. If the last frame is bad quality or skewed or distorted in any way, THAT is your starting image for the next generation. This workflow takes some older ideas and in my opinion isn't all that efficient in what it does, but it works. I'm also not 100% convinced the custom nodes are necessary for what the outcome is. But, hey, the guy made the thing and put it out there, so good for him and everyone that is getting use out it! The video is dubbed in English, has Spanish original audio and all the comments are in Spanish, so use the Google Translate links on them.


Learning how to use it, though, gave me an idea. There is likely already a custom node or suite that does what I'm thinking of testing today, but with the vastness of the internet I've not come across it in my searches. I've tried the idea of taking the last frame and using it as the first of the next, both manually and using stock nodes to accomplish it. What I'm trying is 100% manual upfront, at least, and hopefully the rest will work by itself. On my rig and the nature of First Frame Last Frame Wan nodes it will not be fast at all. In fact I expect it will take at least twice as long for each 5 second clip. But I'm hoping the output will be worth it.

Basic Concept

I will generate a 5 second (or longer, I suppose) video of something. Add a Save Image node near the Video Combine node to save out all the frames to a folder. With any video, the output frames will vary in quality due to the motion of the overall video, but there WILL BE frames among them that look better then adjacent ones. For every motion your character does in your video, be that walking, dancing, sex acts, whatever (I'm all for the latter) there will be the very first frame of an action and the last frame of an action. Those should be the most clear and best quality of the bunch, I'm thinking. I will try to find a number of such frames among 161 frames at the end of an interpolated video generation. Those are the frames I will then use in a recursive First Frame, Last Frame workflow. Sounds right in my head, so I'll give that a shot.
 
  • Like
Reactions: CoolKevin
Wow forgot to mention some important details so I will do that now as to not come across as disingenuous. :D

My comparative test I'm doing will be using just a straight Wan 2.2 Image-to-Video workflow to generate VideoA. The workflow will also save out every uncompressed frame of the output video. For the firts control workflow I will then feed the uncompressed last frame back in, only change the seed, and run it again. I will repeat this process (using the new last frame as the image input) until there are 5 output videos in addition to VideoA. I'll combine them all sequentially to see the results.

The new workflow is a First/Last Frame generation. I will take the last uncompressed frame of VideoA as the starting image and curate the end image from among all the other uncompressed frames repeatedly and generate with same prompt, different seed as above until I again have 5 additional output files. Then I'll combine those all sequentially to compare the results of the two.
 
Okay, so here is the prompt used on every run of individual clips that were later combined:

(bl0wj0b:1.2), POV cock in a woman's hand, thrusting in and out repeatedly, <lora: DR34ML4Y_I2V_14B_LOW.safetensors:1.0>,

This is using the dual High/Low Noise DR34ML4Y_I2V_14B LoRAs with one of its trigger words and Wan 2.2 as the video model.

The CONTROL Generated Video

Used starting image:
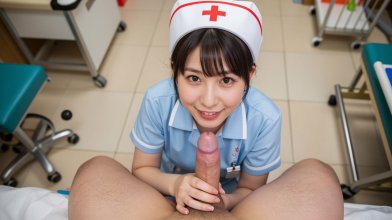
z-image_00585_.jpg

Used a standard Wan 2.2 workflow to created 00.mp4
Used last uncompressed frame of 00.mp4 as the starting frame for 01.mp4 generation, same exact workflow and prompt.
Used last uncompressed frame of 01.mp4 as the starting frame for 02.mp4 generation [same].
Used last uncompressed frame of 02.mp4 as the starting frame for 03.mp4 generation [same].
Used last uncompressed frame of 03.mp4 as the starting frame for 04.mp4 generation [same].
Used last uncompressed frame of 04.mp4 as the starting frame for 05.mp4 generation [same].

Here is the sequence of starting images from last frames after the very first full sized source image:
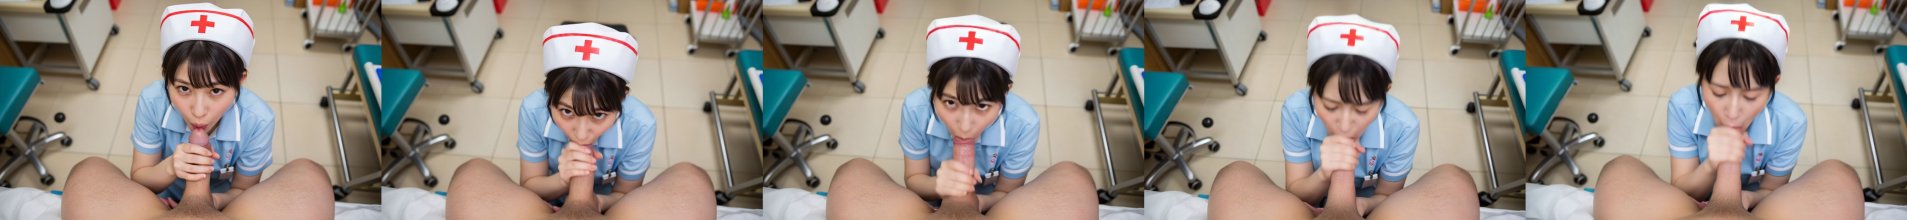
sequence.jpg

These were the 5 starting last frame images for 01.mp4 thru 05.mp4. Then I combined 00.mp4 thru 05.mp4 into Control.mp4.

The GUIDED Generated Video

For each video clip I started by using a curated first and last uncompressed frame out of the initial 00.mp4, of course starting with the very first frame of 00.mp4, not even the starting full size image (although I should have for this comparison :oops:). Here is the exact sequence, (I goofed and only generated 5 total clips here, but I think it proves a point as-is)

Start/End frame of G00.mp4
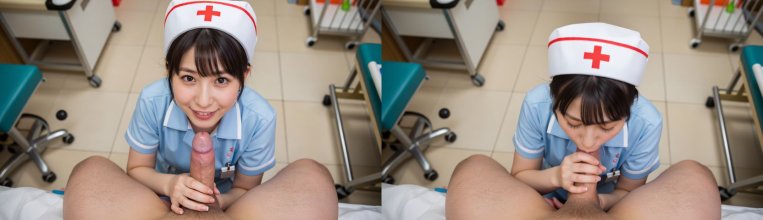
01.jpg

Start/End frame of G01.mp4
02.jpg

Start/End frame of G02.mp4
03.jpg

Start/End frame of G03.mp4
04.jpg

Start/End frame of G04.mp4 (ended the last frame as the first frame of all this, it creates a nice loop)
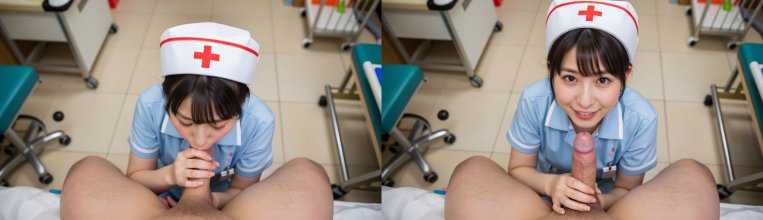
05.jpg

You can hopefully already see the difference in source image quality using curated frames and not just the last frame of the previous video. Like I said in an earlier post it is best to find frames at the very beginning or end of an action from a video, much less blur/mess.

I combined G00.mp4 thru G04.mp4, five total clips. Here are the results for both!

(NOTE: Not sure how I did this! So the Control video is 832x480 and the Guided video is 864x480 and the whole time I intended both to match. Oh well.)

CONTROL

GUIDED

Conclusions

It may just be my opinion to some, but the Guided one looks a whole lot better. Even looking at the starting frames of the Control video clips you can see the further we go using the last image of the previous video just grabs a fuzzy image and the guys penis looks wildly different than when it started. I wonder if that is what contributed to the sudden and continuous slight increase in speed of her actions beginning at the third clip point. Maybe the fuzzy/blurry was understood by Wan 2.2 as fast motion. And by the end of that one hell of a blow/tug job the woman's face is completely different.

The Guided version keeps her face consistent throughout; the man's penis as well, and definitely the motion. I really think that has to do with that blur; Wan must see that as fast motion and it tries to immediately continue with it. Using the very first starting frame as the last clips ending frame was intentional to create the loop. True, you can still see the transitions, but I intend to work on that at some point.

Let me know your opinions! I'd love to hear them. And once I clean up the Guided workflow I'll post it here for anyone that wants to give this a try. :D
 
Last edited: