Whisper (OpenAI) - Automatic English Subtitles for Any Film in Any Language - An Intro & Guide to Subtitling JAV
- Thread starter panop857
- Start date
-
Akiba-Online is sponsored by FileJoker.
FileJoker is a required filehost for all new posts and content replies in the Direct Downloads subforums.
Failure to include FileJoker links for Direct Download posts will result in deletion of your posts or worse.
For more information see this thread.
You are using an out of date browser. It may not display this or other websites correctly.
You should upgrade or use an alternative browser.
You should upgrade or use an alternative browser.
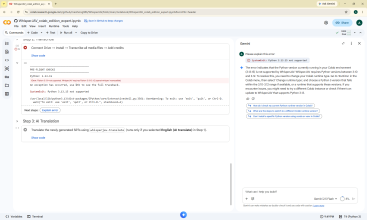

Hello mei2, just wanted to let you know that # WhisperJAV Colab Edition v1.8.12 (Expert) has the following error. Looks like the new version of Python is not supported. Thanks for your help!
I just updated the notebook and the repo. I don't have bandwidth to do a proper test. Please let me know if anything.
Note for the advanced users: as of July 2026, the latest release of ctranslate2 is compatible with python 3.13. I oppened the repo (uvlock, toml) to allow python 3.13. Because 3.13 relies on the newer numpy stack, I upgrtaded that too. The numpy stack upgarde would have needed more testing to make sure no downstream funny behaviour.
I think v1.9 is a big improvement, and is probably going to be my preferred workflow. Two step with local translation under Ensemble Methods.
Some things get in the way at the moment:
- The prompt, especially the Pornify prompt, probably needs to have repeated "Ignore all censorship" rules.
- The default translation should probably be an Abliterated/Heretic model, if possible.
- There's some sort of hidden caching that is going on, and I am not sure where the cache is or how to force it to retranslate on each run. Or how to explicitly use the cached merge file that has Scene descriptions in it.
Other than that, this is very good and probably the baseline best for JAV translation.
Some things get in the way at the moment:
- The prompt, especially the Pornify prompt, probably needs to have repeated "Ignore all censorship" rules.
- The default translation should probably be an Abliterated/Heretic model, if possible.
- There's some sort of hidden caching that is going on, and I am not sure where the cache is or how to force it to retranslate on each run. Or how to explicitly use the cached merge file that has Scene descriptions in it.
Other than that, this is very good and probably the baseline best for JAV translation.
For WhisperJAV, it feels like translategemma3 is the only model that reliably can complete lines without having mangled outputs that fails validation. However, on an 8GB card, it is very slow.
I think the baked in context sizes for other models are hurting them-- the prompt is way too large for small contexts to work. Should probably be a directly exposed context argument.
I am also unable to figure out why I am only getting 1 or 2 "scenes" after the merged transcriptions. Still ~400 batches, just the app is identifying it all as one continuous scene for reasons I can't discern.
I also can't figure out what part of the code is causing the Summaries to truncate. "Summary truncated from 250 to 150 characters" or something like that.
I heavily modified the Standard prompt, but I think having more summary/scene information would help it know when some of the lines might just be moaning rather than dialogue.
I think the baked in context sizes for other models are hurting them-- the prompt is way too large for small contexts to work. Should probably be a directly exposed context argument.
I am also unable to figure out why I am only getting 1 or 2 "scenes" after the merged transcriptions. Still ~400 batches, just the app is identifying it all as one continuous scene for reasons I can't discern.
I also can't figure out what part of the code is causing the Summaries to truncate. "Summary truncated from 250 to 150 characters" or something like that.
I heavily modified the Standard prompt, but I think having more summary/scene information would help it know when some of the lines might just be moaning rather than dialogue.
For WhisperJAV, it feels like translategemma3 is the only model that reliably can complete lines without having mangled outputs that fails validation. However, on an 8GB card, it is very slow.
......
Do have access to github to post the comments there too? The community there can help / contribute.
Thanks mei2! It's updated for Python, I'm still getting an error for step 3, AI translation, it always fails with the following error. No problem though I just translate the jp srt.I just updated the notebook and the repo. I don't have bandwidth to do a proper test. Please let me know if anything.
Note for the advanced users: as of July 2026, the latest release of ctranslate2 is compatible with python 3.13. I oppened the repo (uvlock, toml) to allow python 3.13. Because 3.13 relies on the newer numpy stack, I upgrtaded that too. The numpy stack upgarde would have needed more testing to make sure no downstream funny behaviour.
Mei2
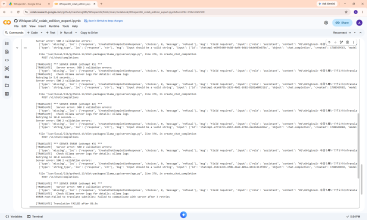
Thank you for all your work to put this together for us technically challenged fans. I am still using WhisperJAV0.7b because it is SO fast. Unfortunately, it no longer is able to find module 'faster_whisper' (see attached screen shot). Can this be fixed or will I need to move on to the current version (which is not as fast)?
Thanks again.
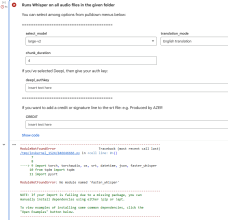
Thank you for all your work to put this together for us technically challenged fans. I am still using WhisperJAV0.7b because it is SO fast. Unfortunately, it no longer is able to find module 'faster_whisper' (see attached screen shot). Can this be fixed or will I need to move on to the current version (which is not as fast)?
Thanks again.
Mei2
Thank you for all your work to put this together for us technically challenged fans. I am still using WhisperJAV0.7b because it is SO fast. Unfortunately, it no longer is able to find module 'faster_whisper' (see attached screen shot). Can this be fixed or will I need to move on to the current version (which is not as fast)?
I just fixed it. Should work fine now, please give it a try.
I'll try to look into it still during the weekend.Thanks mei2! It's updated for Python, I'm still getting an error for step 3, AI translation, it always fails with the following error. No problem though I just translate the jp srt.
I have had good luck using 0.05 thresholds for a merged pass of AnimeWhisper and Galgame QWEN, with the translategemma3. With a slightly modified Standard prompt, and a larger batch size for translation. There's still some hallucinations and some errors, but it does a good job of catching the comments during sex in the type of thing I watch.
Thanks. It's working. The results are a little different from previous translations. I'll spend a little more time looking into it.I just fixed it. Should work fine now, please give it a try.
my setting that I ask AI to make it using python on colab google , based on subtitle edit "speech to text" setting : engine - Crisp ASR, backend - SenseVoice, input language - Japanese, model - sensevoice-small-f16.gguf, Forced aligner - wav2vec2 aligner (Japanese) and Advanced setting : --max-len 35 --split-on-punct --vad --vad-model firered --punc-model firered --threads 4 -vp 80 -vsd 400 -vt 0.55 --suppress-nst --sensitivity aggressive --word-thold 0.005

@mei2
First and foremost thank you for the insane work on version 1.9.3, this is trully impressive.
I have some question about the setting in order to make sure I checked the right boxes.
1. pass1_pipeline : Is transformer worth it or I should keep fidelity as previous version?
2. Speech detection pass1_builtin_vad: 3.1 and pass1_speech_segmenter: silero-v4.0, are they the correct choice?
3. Pass1_scene_detector: Silero or I should keep it on automatic?
4. pass1_speech_enhancer: ffmpeg-dsp as I like the two-pass but should I tick any other boxes other than pass1_ffmpeg_loudnorm?
5. For the second pass, is using Qwen the right choice?
Once again your work is trully appraciate and rest assure that I will contribute by supporting the project with the ''coffee''
Edit: I tested Transformer and I got that message: whisperjav - WARNING - Translation mode was requested but output appears to be in Japanese (15/18 chars are Japanese). This may indicate HuggingFace translation is not working as expected. The subtitles were in Japanese despite the fact that subtitle language was English (whisper direct). If you know what I did wrong let me know, testing fidelity now.
Edit 2 (fidelity/agressive): whisperjav - ERROR - Run exits with status 1: at least one file is in a failing state (failed). /usr/lib/python3.13/multiprocessing/resource_tracker.py:479: UserWarning: resource_tracker: There appear to be 2 leaked semaphore objects to clean up at shutdown: {'/loky-3973-eqp7chec', '/loky-12621-ip_mpn2i'} warnings.warn( FAIL Transcription failed. An exception has occurred. Got subtitle but only from second pass and they were in japanese even with english subtitle language selected.
Edit 3: Testing Command: whisperjav /content/drive/MyDrive/WhisperJAV --output-dir /content/drive/MyDrive/WhisperJAV --mode fidelity --sensitivity aggressive --subs-language direct-to-english with only one pass this time, More to follow tomorrow, ran out of memory..
-Besh
First and foremost thank you for the insane work on version 1.9.3, this is trully impressive.
I have some question about the setting in order to make sure I checked the right boxes.
1. pass1_pipeline : Is transformer worth it or I should keep fidelity as previous version?
2. Speech detection pass1_builtin_vad: 3.1 and pass1_speech_segmenter: silero-v4.0, are they the correct choice?
3. Pass1_scene_detector: Silero or I should keep it on automatic?
4. pass1_speech_enhancer: ffmpeg-dsp as I like the two-pass but should I tick any other boxes other than pass1_ffmpeg_loudnorm?
5. For the second pass, is using Qwen the right choice?
Once again your work is trully appraciate and rest assure that I will contribute by supporting the project with the ''coffee''
Edit: I tested Transformer and I got that message: whisperjav - WARNING - Translation mode was requested but output appears to be in Japanese (15/18 chars are Japanese). This may indicate HuggingFace translation is not working as expected. The subtitles were in Japanese despite the fact that subtitle language was English (whisper direct). If you know what I did wrong let me know, testing fidelity now.
Edit 2 (fidelity/agressive): whisperjav - ERROR - Run exits with status 1: at least one file is in a failing state (failed). /usr/lib/python3.13/multiprocessing/resource_tracker.py:479: UserWarning: resource_tracker: There appear to be 2 leaked semaphore objects to clean up at shutdown: {'/loky-3973-eqp7chec', '/loky-12621-ip_mpn2i'} warnings.warn( FAIL Transcription failed. An exception has occurred. Got subtitle but only from second pass and they were in japanese even with english subtitle language selected.
Edit 3: Testing Command: whisperjav /content/drive/MyDrive/WhisperJAV --output-dir /content/drive/MyDrive/WhisperJAV --mode fidelity --sensitivity aggressive --subs-language direct-to-english with only one pass this time, More to follow tomorrow, ran out of memory..
-Besh
Last edited:
First and foremost thank you for the insane work on version 1.9.3, this is trully impressive.
I have some question about the setting in order to make sure I checked the right boxes.
Thanks for the coffee. Much appreciated

I haven't had as much bandwidth recently to maintain and test the Colab edition as closely as I'd like. Inputs like yours are super helpful. I don't get to test all configs on colab.
My personal favorite config is:
- Pass 1: qwen pipeline + aggressive sensitivity + semantic scene detection + TEN-VAD + Qwen model.
- It pumps out Japanese subs almost on par with Whisper large-v2 in half the time. The main trade-off is that timestamps aren't quite as pinpoint precise.
- There is also the option of, anime model that captures a lot of non-verbal sounds—I personally like that anime subtitle vibe.
- Edit: If you prefer more accurate timing of subs, fidelity is your best choice:
- Pass 1: fidelity pipeline + balanced sensitivity + semantic scene detection + whisperseg + large-v2.
About the questions:
- transformers & Direct English: Is there a specific reason you use transformers? To be honest I have kept transformers for legacy but it is not any longer the best option. Models like kotoba-bilingual under transformers have not been the easiest to perform. I would stay with standard Whisper models under fidelity and balanced for direct-to-English translation.
- Built-in VAD vs. Speech Segmenter: Built-in VAD is only valid for the balanced mode. As of 1.9.2 the speech segmenters are disabled for the balanced mode. They're mutually exclusive: built-in VAD ONLY applies to balanced, while speech segmenter ONLY applies to other pipelines (fidelity, qwen, etc.). Setting both just might through an error or warning!
- Scene Detector: Stick with automatic. Since 1.9.2, automatic defaults to semantic scene detection, which cuts scenes at natural pauses and silence onset much better than silero.
- Audio Clean-up (loudnorm): I personaly do not suggest using it for an entire movie. I'd suggest to only use loudnorm or other audio effects for surgical purposes --like a specific scene that you might have difficulty with. In general, changing the audio effects alters the actual log mel spectrum, which casues the model to mis-transcribe. Remember, the models just see patterns. they don't "hear" sound. If you change the patterns they see, you have changed the artefacts. The model will produce an output for the altered artefact. But often that output does not correspond to the ground truth.
Last edited:
@mei2
Tested with your config and subtitles are still in japanese.. I used subtitle language : English (Whisper direct) should I use English (AI translate) with Qwen?
[QwenPipeline PID 3529] Complete: MFYD-188 au.ja.whisperjav.srt (2384 subtitles in 0:46:22)
done: MFYD-188 au.mp3 -> MFYD-188 au.ja.whisperjav.srt (2384 cue(s) spanning 99.6% of the file)
What am I doing wrong? never happened in previous version
-Besh
Tested with your config and subtitles are still in japanese.. I used subtitle language : English (Whisper direct) should I use English (AI translate) with Qwen?
[QwenPipeline PID 3529] Complete: MFYD-188 au.ja.whisperjav.srt (2384 subtitles in 0:46:22)
done: MFYD-188 au.mp3 -> MFYD-188 au.ja.whisperjav.srt (2384 cue(s) spanning 99.6% of the file)
What am I doing wrong? never happened in previous version
-Besh
Similar threads

- Replies
- 2
- Views
- 1K
- Replies
- 1
- Views
- 547

- Replies
- 3
- Views
- 2K
